





Are we confusing superintelligence with being human?
AI is becoming extraordinarily capable at tasks we associate with human intelligence. As we debate AGI and superintelligence, I think we need to examine what we're actually measuring, how those capabilities translate into the real world, and why intelligence and sentience deserve separate consideration.
Every major AI model release seems to arrive with another set of impressive benchmark results. We’re seeing machines perform at or above human level on increasingly difficult mathematics, science, coding and reasoning tasks, and the conversation quickly turns to how close we are to artificial general intelligence (AGI), or even superintelligence.
I find the progress genuinely exciting, although my background in psychology makes me approach some of these claims with a degree of caution. We’ve spent generations studying human intelligence and still have substantial questions about how cognition, learning, memory and conscious experience interact. I’m increasingly conscious that we’re using human intelligence as the reference point for AI progress, while defining that intelligence through a relatively narrow collection of tasks that we’ve decided machines should be able to complete.
There is also a distinction that I think gets lost in these conversations. Intelligence and sentience are often discussed as though advances in one naturally bring us closer to the other, despite being concerned with quite different things.
What do we mean by AGI and superintelligence?
There isn’t a universally accepted definition of AGI, although the Stanford Institute for Human-Centered Artificial Intelligence describes it in terms of a system’s ability to learn, reason and apply knowledge across a wide range of tasks and domains at approximately human level or above. The emphasis is on breadth of capability, including the ability to handle unfamiliar problems beyond those for which a system was specifically developed.
Google DeepMind’s Levels of AGI framework offers a useful way of making that definition more precise. It separates how broadly a system can apply its capabilities from how well it performs, and considers autonomy as a further dimension. This allows researchers to describe different levels of progress without treating AGI as a single threshold that a model either has or hasn’t crossed.
Superintelligence extends the comparison much further. In its 2026 paper From AGI to ASI, DeepMind explores artificial general superintelligence as intelligence and cognitive capability exceeding that of large organizations of humans, potentially through several different technological pathways.
These are working definitions of capability, and I think that’s important to establish. They’re concerned with what systems can accomplish, not whether they experience curiosity, satisfaction, emotion or anything else while doing it. The question of sentience, whether a system is capable of subjective experience, requires a different kind of evidence.
Are we defining intelligence around what machines can measure?
I have a lot of respect for the research going into AI benchmarks. They give researchers consistent ways to compare models, investigate particular abilities and assess whether new techniques are producing meaningful improvements. Without them, conversations about progress would be considerably more subjective. However, we need to examine what those tests are actually measuring and how far their results can reasonably be generalized.
Many of our most prominent benchmarks are built around tasks with clearly specified objectives and answers that can be evaluated against a defined standard. A mathematics problem, coding challenge or professional examination may require considerable reasoning, but it typically removes much of the ambiguity that characterizes how intelligence is used in the real world.
Consider a physicist working on an unfamiliar problem. The work may involve identifying which questions are worth investigating, recognizing limitations in available evidence, revising assumptions, collaborating with colleagues and deciding when a theoretically promising result is useful enough to pursue. Solving an isolated physics problem can demonstrate exceptional competence without capturing those wider demands.
There’s a problem with how we interpret this kind of performance, particularly when we begin making claims about general intelligence. We select certain tasks as indicators of intelligence, optimize machines to perform well against them, and then use their success as evidence that they are approaching or surpassing human capability more broadly. The tasks aren’t necessarily arbitrary in their difficulty or intellectual demands, but the decision to treat them as representative of intelligence is a human choice.
This becomes especially important when the tasks have limited real-world application. A model may demonstrate sophisticated reasoning under controlled conditions and still struggle to apply that capability consistently when requirements are incomplete, the environment changes or success depends on understanding consequences beyond the immediate task.
Stanford’s 2026 AI Index gives a particularly striking illustration of uneven capability. AI systems have achieved gold-medal performance on International Mathematical Olympiad problems, while leading models still perform substantially worse than humans at reading ordinary analog clocks. The same report describes significant improvements in agents completing computer-based tasks, although they continue to fail a substantial proportion of attempts even in structured evaluations.
I don’t think the conclusion is that benchmarks lack value. Their usefulness depends on whether we’re measuring a particular technical ability, assessing performance in a realistic environment or making a much broader claim about intelligence. Those require different standards of evidence.
The intelligence we experience without thinking about it
One of the things I’ve always found fascinating about psychology is how much information our brains process before we’re consciously aware of having processed anything.
Imagine speaking to someone you know well and immediately sensing that something is different. Perhaps their expression changes briefly, their voice sounds slightly unfamiliar or their response doesn’t quite fit the situation. You form an impression almost instinctively, and that impression may change within moments as the conversation continues.
Behind that apparently effortless interaction, your brain is integrating sensory information with memories of previous encounters, learned social patterns, expectations and the emotional significance of the situation. Some perceptual processes unfold within milliseconds, while other processes involving interpretation, memory and learning develop across longer timescales.
We can study many of these functions individually through neuroscience and cognitive psychology, and research continues to improve our understanding of the mechanisms involved. Yet the way these processes operate together is enormously complex, particularly when we consider how previous experience, attention, motivation and physiological state influence what we perceive and remember.
Much of this happens outside conscious awareness. We don’t deliberately retrieve every relevant memory, examine each facial expression or instruct our brains to update our understanding as new information arrives. We experience the outcome of processes that have already begun shaping our interpretation of the world.
I think this provides important context for how we discuss artificial intelligence. Researchers have developed computational approaches to functions such as pattern recognition, prediction, memory, reasoning and learning, with some drawing inspiration from our understanding of the brain. These capabilities can be combined in increasingly sophisticated systems, although the mechanisms involved can differ considerably from biological cognition.
A language model can use new information presented during a conversation and adjust its responses accordingly. An agent can retrieve memories, use tools, respond to feedback and change its approach to a task. These are meaningful forms of adaptation, although updating a model’s context or an external memory store isn’t necessarily equivalent to changing its underlying learned parameters, and neither mechanism directly reproduces the full range of human learning processes.
I wouldn’t argue that artificial intelligence needs to recreate human biology to become generally intelligent. We’re already demonstrating that machines can achieve extraordinary results through mechanisms that differ from our own, and future systems may develop forms of intelligence that don’t have a close human equivalent.
The comparison does, however, raise questions about how much we can infer from performance alone. Producing the same answer as a human doesn’t mean a system arrived there through the same processes, just as displaying intelligent behavior doesn’t establish that it has any subjective experience.
Superhuman intelligence doesn’t establish sentience
Consider a future AI system capable of solving mathematical or theoretical physics problems beyond the abilities of the world’s leading researchers. It identifies patterns nobody has recognized, develops new proofs and produces discoveries that might otherwise have taken decades of human effort. Assuming those results can be verified, we’d have strong evidence of extraordinary intellectual capability, and if that competence extended across sufficiently broad domains, it could contribute to a case for superintelligence.
We would still know remarkably little about whether the system experienced anything while producing those results.
A human mathematician might spend years working on a problem, driven by curiosity, professional ambition, frustration or the satisfaction of finally understanding something. Their work draws on knowledge and experience accumulated over a lifetime, alongside cognitive processes that may be difficult for them to describe.
A machine could reach the same conclusions, or substantially better ones, through an entirely different process. The quality of its achievement would tell us something about its intelligence, but it wouldn’t establish whether the system felt curiosity, frustration or satisfaction along the way.
I think we naturally associate exceptional intellectual achievement with the experiences of the person responsible for it. As machines begin producing results that previously required remarkable human expertise, it’s tempting to transfer those assumptions to the systems themselves.
The science doesn’t currently give us grounds to make that leap. Researchers continue to disagree about whether artificial systems could possess consciousness, how it might arise and how we would recognize it. A recent Nature commentary by Anil Seth, Ned Block and Giulio Tononi argues that intelligence alone is insufficient evidence of subjective experience, while other researchers take different positions on the possibility of machine consciousness.
We can recognize a machine as highly intelligent without assuming it is sentient, and we can investigate the possibility of machine sentience without making it a prerequisite for AGI. Both questions deserve rigorous research, with evidence appropriate to what we’re trying to establish.
What this means when we put AI to work
There’s a practical consequence to these distinctions that I think deserves more attention as organizations start giving agents greater responsibility.
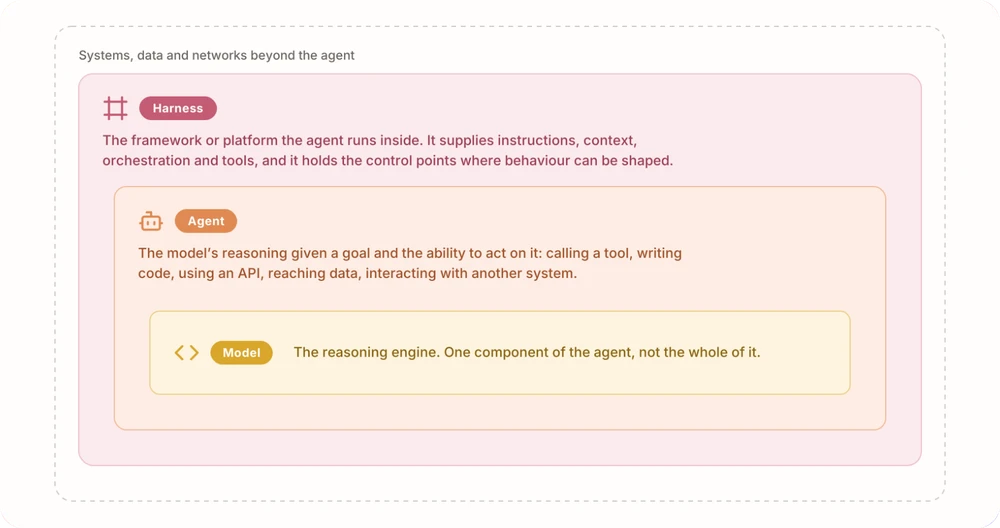
A benchmark may demonstrate that a model can reason through a difficult problem or complete a particular workflow. Once that model becomes part of an agent operating across business systems, its performance also depends on the information it encounters, the tools available to it, the permissions it holds and how it responds when circumstances don’t match the conditions under which it was evaluated.
Real environments introduce changing priorities, incomplete information, conflicting instructions and consequences that may only become apparent much later. A system can be extremely capable at the tasks it has been tested against and still behave unexpectedly when those tasks form part of a larger, less predictable process.
This is why I think the move towards agentic AI warrants careful attention independently of progress towards AGI. Organizations are already giving systems the ability to act on information, make decisions and influence operational outcomes. Those capabilities create opportunities and responsibilities whether the underlying models qualify as generally intelligent, superintelligent or neither.
Teams need to understand how an agent performs in the context of the work they expect it to carry out. That includes testing how it handles uncertainty, what it does when a task changes, how it uses information and tools, and whether the boundaries placed around its activity remain appropriate as it operates.
Sentience isn’t a useful proxy for making those decisions. An agent doesn’t need subjective experience to make a consequential error, discover an effective way to achieve a goal or produce valuable work.
What are we actually trying to understand?
I expect AI will continue surpassing average human performance across an increasingly broad range of activities, and we may eventually develop systems whose capabilities justify the term superintelligence. The progress in mathematics, science and other specialized fields already gives us good reasons to take that possibility seriously.
My concern is how readily we turn performance on selected tasks into much wider assumptions about intelligence, particularly when those tasks don’t adequately represent the conditions in which people apply their abilities. Psychology has a long history of grappling with the difficulty of measuring complex human characteristics through observable tests. The validity of those measures depends on how well they capture the underlying capability, and on recognizing what falls outside the evaluation.
AI research faces a similar challenge, with the additional complication that we’re comparing computational systems against human abilities that arise from very different mechanisms. We need evaluations that examine breadth, adaptability and performance in realistic environments, alongside the specialized benchmarks that have been so useful in driving progress.
I also think we need to preserve the distinction between intelligence and sentience as these systems advance. A machine may eventually exceed human cognitive capabilities across almost every measurable domain without that achievement resolving whether it has any subjective experience. Equally, uncertainty about consciousness shouldn’t prevent us from recognizing or taking responsibility for the capabilities that machines demonstrably possess.
The definitions we choose will influence the research we prioritize, the systems we develop and the expectations we place on them. If we’re going to use human intelligence as the benchmark for AGI and superintelligence, we should be as rigorous about understanding the human side of that comparison as we are about measuring the machines.